Puppeteer
Puppeteer: how a headless browser sees your site
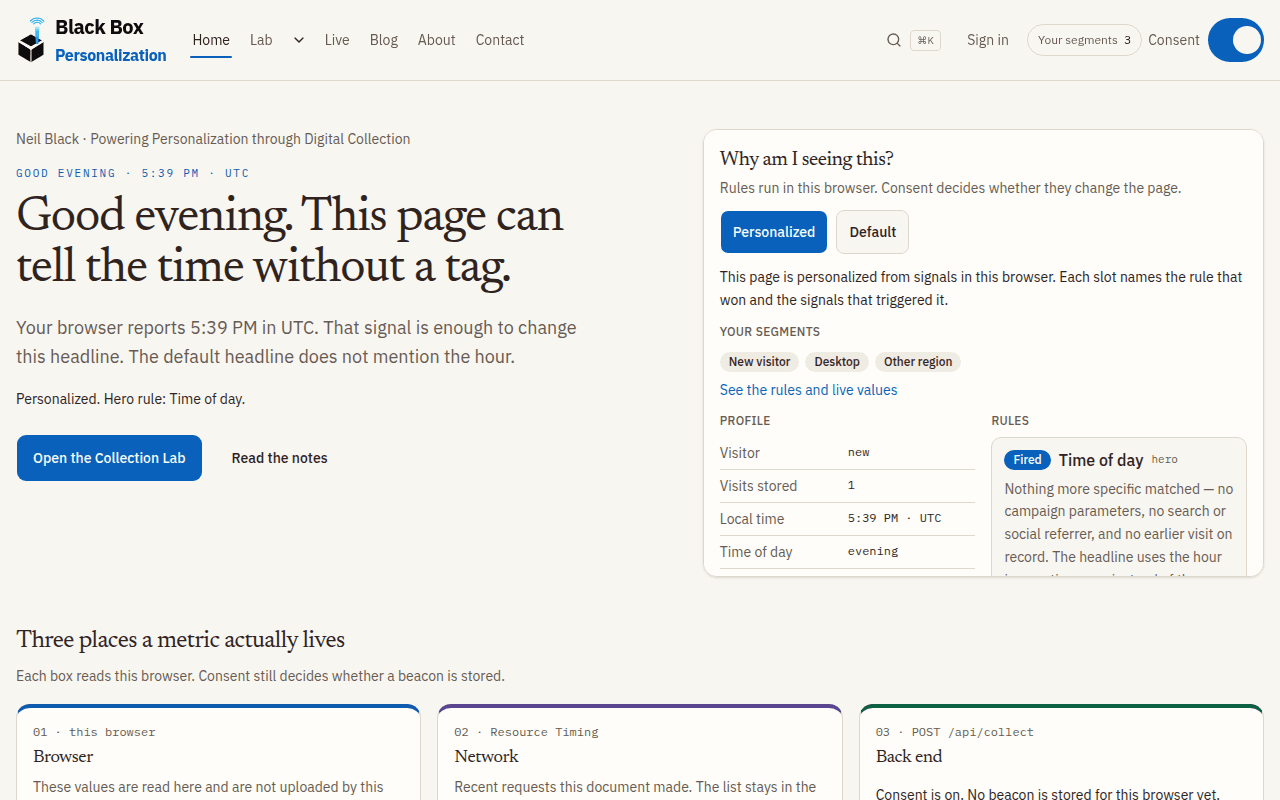
A Node script can open this site in Chrome without a window, click Accept, and read the same dataLayer and GA4 hits a browser would send. This page is that walk, with the output of one real run.
What it is
Puppeteer is a Node.js library that drives Chrome. The Chrome team at Google built it. The docs are at pptr.dev.
“Headless” means Chrome still loads the page, runs the JavaScript, and paints the pixels, but it does not open a window. The script asks for a heading, a click, or a screenshot, and Chrome answers. Analytics folks use it when a check has to see the page the way a browser does, not the way a plain HTTP client does.
Opening this lab pushes the usual page_view after consent, with page_path set to /lab/puppeteer. The GA4 config keeps send_page_view false, so that push is the page event. dataLayer shows the same path from the queue to the hit.
How it works
Node does not talk to the page directly. It talks to Chrome, and Chrome talks to the page.
Step 1
Node script
The script calls launch, goto, click, and evaluate. It never draws the page itself.
Step 2
DevTools Protocol
Each call becomes a JSON command on a WebSocket. Chrome answers on the same socket.
Step 3
Headless Chrome
Chrome loads the site, runs its JavaScript, and has no window on the screen.
What analytics teams use it for
Automated tag QA
Open a page, accept consent, and fail the run if page_view is missing from the queue or from /g/collect.
dataLayer after consent
Read the queue before Accept and again after. On this site the event rows appear only once consent is granted.
Screenshots
Save the pixels Chrome painted. That is the page a person would have seen, including text that JavaScript wrote.
Synthetic monitoring
Run the same script on a schedule. A missing heading, a missing hit, or a failed navigation is an alert, not a hunch.
Performance and Web Vitals
The page can read PerformanceObserver entries the same way the Collection Lab reads them in a normal browser.
SEO rendering checks
Read the DOM after JavaScript. A crawler that does not run scripts never sees that rendered heading.
The script, in pieces
These blocks are slices of the script that produced the recording below. Copy them in this order. The listener has to be registered before the page opens.
Launch
puppeteer-core speaks the protocol and uses a Chrome you already have. The puppeteer package is the same API with a browser download included. This recording used puppeteer-core 24 and the Chrome on the machine.
import puppeteer from "puppeteer-core"

const browser = await puppeteer.launch({
  executablePath: "/usr/bin/google-chrome",
  headless: true,
  args: ["--no-sandbox", "--disable-dev-shm-usage"],
})
const page = await browser.newPage()
await page.setViewport({ width: 1280, height: 800 })
Intercept collect hits
Register the listener before navigation. A hit that leaves during goto is otherwise already gone. GA4 posts to /g/collect. One POST can carry several events, one query string per line.
const hits = []
page.on("request", (request) => {
  const url = request.url()
  if (!url.includes("google-analytics.com") || !url.includes("/g/collect")) return
  hits.push({
    method: request.method(),
    url,
    body: request.postData() || "",
  })
})

function eventNames(url, body) {
  const parsed = new URL(url)
  const chunks = [parsed.search.slice(1), ...body.split(/\n/).map((line) => line.trim()).filter(Boolean)]
  const names = []
  for (const chunk of chunks) {
    const name = new URLSearchParams(chunk).get("en")
    if (name) names.push(name)
  }
  return names
}
Open the page
goto drives Chrome to the URL and waits until the document has loaded. waitForSelector holds the script until the hero heading exists, which means JavaScript has rendered the page.
const target = "https://blackbox-site-eta.vercel.app/"
await page.goto(target, { waitUntil: "domcontentloaded", timeout: 45000 })
await page.waitForSelector("h1")
Read the dataLayer
page.evaluate runs in the page. dataLayer rows are argument lists, so Array.from turns each one into a real array before it can cross back to Node.
const before = await page.evaluate(() =>
  JSON.parse(JSON.stringify({
    userAgent: navigator.userAgent,
    webdriver: navigator.webdriver,
    dataLayer: (window.dataLayer || []).map((entry) => Array.from(entry)),
  }))
)
Click Accept
The consent banner is a button labeled Accept. Clicking it is what a person does. Until that click, this site does not push measurement events and does not send a collect hit for them.
const clickedAccept = await page.evaluate(() => {
  const button = [...document.querySelectorAll("button")].find((node) => node.textContent.trim() === "Accept")
  if (!button) return false
  button.click()
  return true
})

await page.waitForFunction(() =>
  (window.dataLayer || []).some((entry) => {
    const list = Array.from(entry)
    return list[0] === "event" && list[1] === "page_view"
  })
)
Screenshot
The picture is the pixels Chrome painted, not a drawing of the HTML. Close the browser when the script is finished so the process does not keep running.
await page.screenshot({ path: "puppeteer-home.png" })
await browser.close()
What that run saw
One script ran at 3 October 2026, 17:39 UTC against https://blackbox-site-eta.vercel.app/. The viewport was 1280 by 800. Accept was clicked. This page does not launch a browser: a headless Chrome on every request would be slow, easy to loop, and a poor fit for a short serverless function.
User-Agent
Mozilla/5.0 (X11; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) HeadlessChrome/148.0.0.0 Safari/537.36
What the page reported
- navigator.webdriver
- true
- Next.js userAgent()
- Chrome Headless on Linux. is_bot is false.
Queue before Accept
- consent default · analytics_storage: denied, ad_storage: denied, ad_user_data: denied, ad_personalization: denied, wait_for_update: 500
- js Date
- config G-JDE6BF33RY
- consent update · analytics_storage: denied, ad_storage: denied, ad_user_data: denied, ad_personalization: denied
Queue after Accept
- consent default · analytics_storage: denied, ad_storage: denied, ad_user_data: denied, ad_personalization: denied, wait_for_update: 500
- js Date
- config G-JDE6BF33RY
- consent update · analytics_storage: denied, ad_storage: denied, ad_user_data: denied, ad_personalization: denied
- event consent_update · analytics_granted: true
- event segment_update · segments: desktop
- set user_properties · segments: desktop
- consent update · analytics_storage: granted, ad_storage: denied, ad_user_data: denied, ad_personalization: denied
- event page_view · page_location: https://blackbox-site-eta.vercel.app/, page_path: /, page_title: Black Box Personalization, page_referrer:
- event personalization_exposure · personalization_rule: hero:time-of-day,cta:baseline-cta,recommendations:date-order,layout:standard-weight
- event segment_update · segments: new-visitor,desktop
- set user_properties · segments: new-visitor,desktop
- event segment_update · segments: new-visitor,desktop,other-region
- set user_properties · segments: new-visitor,desktop,other-region
Before Accept the queue holds the consent default, the tag startup, and a consent update that is still denied. There is no page_view. After Accept the same queue gains consent_update, segment_update, page_view, and personalization_exposure. Tag rows with no command name are left out.
Collect hits
Three POSTs reached www.google-analytics.com/g/collect. The first two left while consent was still denied, so their gcs is G100. The third is one batch: user_engagement, page_view, personalization_exposure, and two segment_update events, with gcs G101. page_view does not repeat the path as an event parameter. The document location is the shared dl field, which is the home page URL. The screen size on the hit is 800x600, the headless default, even though the script set a 1280 by 800 viewport. Transport fields such as gtm and gcd are omitted so the event fields stay readable.
Request 1 · POST /g/collect
G100 means analytics storage was still denied when this hit left.
- tid
- G-JDE6BF33RY
- gcs
- G100
- cid
- 1081073262.1791049135
- sid
- 1791049135
- dl
- https://blackbox-site-eta.vercel.app/
- dt
- Black Box Personalization
- sr
- 800x600
consent_update
ep.analytics_granted=true
Request 2 · POST /g/collect
G100 means analytics storage was still denied when this hit left.
- tid
- G-JDE6BF33RY
- gcs
- G100
- cid
- 1081073262.1791049135
- sid
- 1791049135
- dl
- https://blackbox-site-eta.vercel.app/
- dt
- Black Box Personalization
- sr
- 800x600
segment_update
ep.segments=desktop
Request 3 · POST /g/collect
G101 means analytics storage was granted and ad storage stayed denied.
- tid
- G-JDE6BF33RY
- gcs
- G101
- cid
- 1081073262.1791049135
- sid
- 1791049135
- dl
- https://blackbox-site-eta.vercel.app/
- dt
- Black Box Personalization
- sr
- 800x600
user_engagement
ep.ga_temp_client_id=1081073262.1791049135 · up.segments=desktop
page_view
No event parameters on this row. The page URL is dl above.
personalization_exposure
ep.personalization_rule=hero:time-of-day,cta:baseline-cta,recommendations:date-order,layout:standard-weight
segment_update
ep.segments=new-visitor,desktop
segment_update
ep.segments=new-visitor,desktop,other-region · up.segments=new-visitor,desktop
Bots, and numbers that are not people
Sites notice automated browsers in a few ordinary ways. The User-Agent string may say HeadlessChrome, or it may name a known crawler. navigator.webdriver is true under Puppeteer unless the script turns it off. The screen size, the missing window, and a click that happens the instant the button exists are other tells. None of those are perfect. A script can change its User-Agent and move a mouse.
Unfiltered bot traffic lands in the same reports as people. Page views, events, and landing pages move. A script that clicks Accept looks opted in, so Consent Mode lets the hits through. Bounce rate, engagement, and realtime all shift, and a tag QA run is indistinguishable from a visitor unless something marks the difference.
This site does not drop that traffic. robots.txt allows / and asks crawlers to skip /account, /admin, and /api. That is a hint to polite crawlers. It does not stop Chrome, and it does not remove a hit from Google Analytics.
POST /api/collect returns 403 when consent is not granted. It does not read the User-Agent to refuse a bot. When a consented beacon is stored, Next.js userAgent() sets is_bot from a fixed list of crawler names, including Googlebot, Bingbot, Slackbot, and GPTBot. HeadlessChrome is not on that list. For the User-Agent in the run above, the parser says Chrome Headless and is_bot is false.
Nothing in the collect route, the pathing counts, the recommendations, or the GA tag reads is_bot. The flag is stored on the enriched record, so the Collection Lab JSON can show it. It is a label. A headless visit that clicks Accept is measured like any other browser.
Recommended next
Why these picksReading path transitions…